
Label guide#
Basic labelling#
All ArviZ plotting functions and some stats functions can take an optional labeller argument.
By default, labels show the variable name.
Multidimensional variables also show the coordinate value.
Example: Default labelling#
In [1]: import arviz as az
   ...: az.style.use("arviz-variat")
   ...: schools = az.load_arviz_data("centered_eight")
   ...: az.summary(schools)
   ...:
Out[1]:
                        mean   sd eti89_lb eti89_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
mu                       4.2  3.3     -1.2      9.2      240      212  1.03      0.21   0.088
theta[Choate]            6.4  5.9     -1.7       17      572      732  1.01      0.25     0.2
theta[Deerfield]           5  4.9       -3       12      531      851  1.01      0.21    0.15
theta[Phillips Andover]  3.4  5.4     -5.7       11      510      724  1.01      0.23    0.17
theta[Phillips Exeter]   4.8  5.2     -3.1       13      571      588  1.01      0.21    0.21
theta[Hotchkiss]         3.5  4.8     -4.3       11      347      737  1.02      0.25    0.15
theta[Lawrenceville]     3.7  5.2     -4.4       11      505      822  1.01      0.22    0.21
theta[St. Paul's]        6.5  5.2       -1       16      527      766  1.01      0.22    0.15
theta[Mt. Hermon]        4.8  5.7     -3.8       14      537      842  1.01      0.24    0.23
tau                      4.3    3      1.3       10      127      138  1.03      0.22    0.14
ArviZ supports label based indexing powered by xarray. Through label based indexing, you can use labels to plot a subset of selected variables.
Example: Label based indexing#
For a case where the coordinate values shown for the theta variable coordinate to the school dimension,
you can indicate ArviZ to plot tau by including it in the var_names argument to inspect its 1.03 rhat() value.
To inspect the theta values for the Choate and St. Paul's coordinates, you can include theta in var_names and use the coords argument to select only these two coordinate values.
You can generate this plot with the following command:
In [2]: az.plot_trace_dist(
   ...:     schools,
   ...:     var_names=["tau", "theta"],
   ...:     coords={"school": ["Choate", "St. Paul's"]},
   ...:     compact=False
   ...: );
   ...:
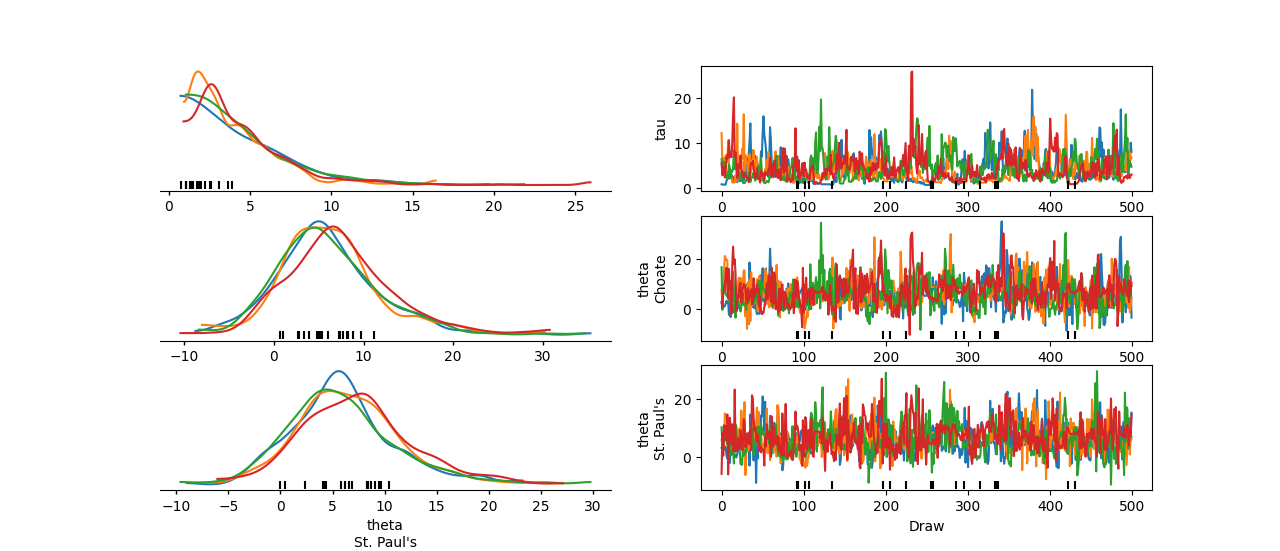
Using the above command, you can now identify issues for low tau values.
Example: Using the labeller argument#
You can use the labeller argument to customize labels.
Unlike the default labels that show theta, not \(\theta\) (generated from $\theta$ using \(\LaTeX\)), the labeller argument presents the labels with proper math notation.
You can use MapLabeller to rename the variable theta to $\theta$, as shown in the following example:
In [3]: from arviz import labels as azl
   ...: labeller = azl.MapLabeller(var_name_map={"theta": r"$\theta$"})
   ...: coords = {"school": ["Deerfield", "Hotchkiss", "Lawrenceville"]}
   ...:

In [4]: az.plot_dist(
   ...:     schools,
   ...:     var_names="theta",
   ...:     coords=coords,
   ...:     labeller=labeller
   ...: );
   ...:

See also
For a list of labellers available in ArviZ, see the the API reference page.
Sorting labels#
ArviZ allows labels to be sorted in two ways:
Using the arguments passed to ArviZ plotting functions
Sorting the underlying
xarray.Dataset
The first option is more suitable for single time ordering whereas the second option is more suitable for sorting plots consistently.
Note
Both ways are limited.
Multidimensional variables can not be separated.
For example, it is possible to sort theta, mu, or tau in any order, and within theta to sort the schools in any order, but it is not possible to sort half of the schools, then mu and tau and then the rest of the schools.
Sorting variable names#
In [5]: var_order = ["theta", "mu", "tau"]
For variable names to appear sorted when calling ArviZ functions, pass a sorted list of the variable names.
In [6]: az.summary(schools, var_names=var_order)
Out[6]:
                        mean   sd eti89_lb eti89_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
theta[Choate]            6.4  5.9     -1.7       17      572      732  1.01      0.25     0.2
theta[Deerfield]           5  4.9       -3       12      531      851  1.01      0.21    0.15
theta[Phillips Andover]  3.4  5.4     -5.7       11      510      724  1.01      0.23    0.17
theta[Phillips Exeter]   4.8  5.2     -3.1       13      571      588  1.01      0.21    0.21
theta[Hotchkiss]         3.5  4.8     -4.3       11      347      737  1.02      0.25    0.15
theta[Lawrenceville]     3.7  5.2     -4.4       11      505      822  1.01      0.22    0.21
theta[St. Paul's]        6.5  5.2       -1       16      527      766  1.01      0.22    0.15
theta[Mt. Hermon]        4.8  5.7     -3.8       14      537      842  1.01      0.24    0.23
mu                       4.2  3.3     -1.2      9.2      240      212  1.03      0.21   0.088
tau                      4.3    3      1.3       10      127      138  1.03      0.22    0.14
ArviZ’s posterior group is a DataTree. To reorder
its variables, subset the underlying Dataset (via
.dataset) with a sorted list of variable names.
In [7]: az.summary(schools.posterior.dataset[var_order])
Out[7]:
                        mean   sd eti89_lb eti89_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
theta[Choate]            6.4  5.9     -1.7       17      572      732  1.01      0.25     0.2
theta[Deerfield]           5  4.9       -3       12      531      851  1.01      0.21    0.15
theta[Phillips Andover]  3.4  5.4     -5.7       11      510      724  1.01      0.23    0.17
theta[Phillips Exeter]   4.8  5.2     -3.1       13      571      588  1.01      0.21    0.21
theta[Hotchkiss]         3.5  4.8     -4.3       11      347      737  1.02      0.25    0.15
theta[Lawrenceville]     3.7  5.2     -4.4       11      505      822  1.01      0.22    0.21
theta[St. Paul's]        6.5  5.2       -1       16      527      766  1.01      0.22    0.15
theta[Mt. Hermon]        4.8  5.7     -3.8       14      537      842  1.01      0.24    0.23
mu                       4.2  3.3     -1.2      9.2      240      212  1.03      0.21   0.088
tau                      4.3    3      1.3       10      127      138  1.03      0.22    0.14
Sorting coordinate values#
For sorting coordinate values, first, define the order, then store it, and use the result to sort the coordinate values. You can define the order by creating a list manually or by using xarray objects as illustrated in the below example “Sorting out the schools by mean”.
Example: Sorting the schools by mean#
Locate the means of each school by using the following command:
In [8]: school_means = schools.posterior["theta"].mean(("chain", "draw"))
   ...: school_means
   ...:
Out[8]:
<xarray.DataArray 'theta' (school: 8)> Size: 64B
array([6.42044255, 4.95449743, 3.42293245, 4.7535654 , 3.45303468,
       3.66295895, 6.50522692, 4.81977956])
Coordinates:
  * school   (school) <U16 512B 'Choate' 'Deerfield' ... 'Mt. Hermon'
You can use the
DataArrayresult to sort the coordinate values fortheta.
There are two ways of sorting:
Arviz args
xarray
Sort the coordinate values to pass them as a coords argument and choose the order of the rows.
In [9]: sorted_schools = schools.posterior["school"].sortby(school_means)
   ...: az.summary(schools, var_names="theta", coords={"school": sorted_schools})
   ...:
Out[9]:
                        mean   sd eti89_lb eti89_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
theta[Phillips Andover]  3.4  5.4     -5.7       11      510      724  1.01      0.23    0.17
theta[Hotchkiss]         3.5  4.8     -4.3       11      347      737  1.02      0.25    0.15
theta[Lawrenceville]     3.7  5.2     -4.4       11      505      822  1.01      0.22    0.21
theta[Phillips Exeter]   4.8  5.2     -3.1       13      571      588  1.01      0.21    0.21
theta[Mt. Hermon]        4.8  5.7     -3.8       14      537      842  1.01      0.24    0.23
theta[Deerfield]           5  4.9       -3       12      531      851  1.01      0.21    0.15
theta[Choate]            6.4  5.9     -1.7       17      572      732  1.01      0.25     0.2
theta[St. Paul's]        6.5  5.2       -1       16      527      766  1.01      0.22    0.15
DataTree does not implement sortby() directly.
Apply it to the underlying Dataset (via .dataset).
In [10]: az.summary(schools.posterior.dataset.sortby(school_means), var_names="theta")
Out[10]:
                        mean   sd eti89_lb eti89_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
theta[Phillips Andover]  3.4  5.4     -5.7       11      510      724  1.01      0.23    0.17
theta[Hotchkiss]         3.5  4.8     -4.3       11      347      737  1.02      0.25    0.15
theta[Lawrenceville]     3.7  5.2     -4.4       11      505      822  1.01      0.22    0.21
theta[Phillips Exeter]   4.8  5.2     -3.1       13      571      588  1.01      0.21    0.21
theta[Mt. Hermon]        4.8  5.7     -3.8       14      537      842  1.01      0.24    0.23
theta[Deerfield]           5  4.9       -3       12      531      851  1.01      0.21    0.15
theta[Choate]            6.4  5.9     -1.7       17      572      732  1.01      0.25     0.2
theta[St. Paul's]        6.5  5.2       -1       16      527      766  1.01      0.22    0.15
Sorting dimensions#
In some cases, our multidimensional variables may not have only one more dimension (a length n dimension
in addition to the chain and draw ones)
but could have multiple more dimensions.
Let’s imagine we have performed a set of fixed experiments on several days to multiple subjects,
three data dimensions overall.
We will create fake inference data with data mimicking this situation to show how to sort dimensions.
To keep things short and not clutter the guide too much with unnecessary output lines,
we will stick to a posterior of a single variable and the dimension sizes will be 2, 3, 4.
In [11]: from numpy.random import default_rng
   ....: import pandas as pd
   ....: rng = default_rng()
   ....: samples = rng.normal(size=(4, 500, 2, 3, 4))
   ....: coords = {
   ....:     "subject": ["ecoli", "pseudomonas", "clostridium"],
   ....:     "date": ["1-3-2020", "2-4-2020", "1-5-2020", "1-6-2020"],
   ....:     "experiment": [1, 2]
   ....: }
   ....: experiments = az.from_dict(
   ....:     {"posterior": {"b": samples}}, dims={"b": ["experiment", "subject", "date"]}, coords=coords
   ....: )
   ....: experiments.posterior
   ....:
Out[11]:
<xarray.DataTree 'posterior'>
Group: /posterior
    Dimensions:     (chain: 4, draw: 500, experiment: 2, subject: 3, date: 4)
    Coordinates:
      * chain       (chain) int64 32B 0 1 2 3
      * draw        (draw) int64 4kB 0 1 2 3 4 5 6 7 ... 493 494 495 496 497 498 499
      * experiment  (experiment) int64 16B 1 2
      * subject     (subject) <U11 132B 'ecoli' 'pseudomonas' 'clostridium'
      * date        (date) <U8 128B '1-3-2020' '2-4-2020' '1-5-2020' '1-6-2020'
    Data variables:
        b           (chain, draw, experiment, subject, date) float64 384kB 0.2291...
    Attributes:
        created_at:                 2026-11-17T21:50:26.480168+00:00
        creation_library:           ArviZ
        creation_library_version:   1.3.1
        creation_library_language:  Python
        sample_dims:                ['chain', 'draw']
Given how we have constructed our dataset, the default order is experiment, subject, date.
Click to see the default summary
In [12]: az.summary(experiments)
Out[12]:
                              mean    sd eti89_lb eti89_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
b[1, ecoli, 1-3-2020]         0.01  1.01     -1.6      1.6     2059     1804  1.00     0.022   0.018
b[1, ecoli, 2-4-2020]            0  0.99     -1.6      1.6     1940     1898  1.00     0.022   0.015
b[1, ecoli, 1-5-2020]         0.01  1.01     -1.6      1.7     2073     1987  1.00     0.022   0.016
b[1, ecoli, 1-6-2020]         0.01  0.99     -1.6      1.6     1981     2062  1.00     0.022   0.015
b[1, pseudomonas, 1-3-2020]   0.03  1.01     -1.6      1.6     1884     1970  1.00     0.023   0.016
b[1, pseudomonas, 2-4-2020]   0.02  1.01     -1.6      1.6     1934     2082  1.00     0.023   0.016
b[1, pseudomonas, 1-5-2020]  -0.03  0.98     -1.6      1.6     1889     1824  1.00     0.023   0.016
b[1, pseudomonas, 1-6-2020]  -0.01  1.02     -1.6      1.7     2011     1790  1.00     0.023   0.016
b[1, clostridium, 1-3-2020]  -0.01  0.97     -1.6      1.5     1809     1821  1.00     0.023   0.016
b[1, clostridium, 2-4-2020]   0.02  1.01     -1.6      1.6     1997     1798  1.00     0.023   0.016
b[1, clostridium, 1-5-2020]  -0.02  1.01     -1.7      1.6     2037     1899  1.00     0.022   0.016
b[1, clostridium, 1-6-2020]   0.04  1.01     -1.5      1.7     2057     1880  1.00     0.022   0.016
b[2, ecoli, 1-3-2020]            0  0.98     -1.6      1.6     2037     1739  1.00     0.022   0.016
b[2, ecoli, 2-4-2020]        -0.07     1     -1.7      1.5     1805     1892  1.00     0.023   0.016
b[2, ecoli, 1-5-2020]            0  0.98     -1.5      1.6     2063     2059  1.00     0.022   0.017
b[2, ecoli, 1-6-2020]        -0.02  1.03     -1.7      1.6     2098     2003  1.00     0.022   0.017
b[2, pseudomonas, 1-3-2020]  -0.02  1.03     -1.6      1.6     1985     2035  1.00     0.023   0.016
b[2, pseudomonas, 2-4-2020]  -0.04  1.01     -1.6      1.6     2075     1921  1.00     0.022   0.016
b[2, pseudomonas, 1-5-2020]     -0     1     -1.6      1.6     1928     1884  1.00     0.023   0.015
b[2, pseudomonas, 1-6-2020]   0.03  0.99     -1.5      1.6     1990     1930  1.00     0.022   0.015
b[2, clostridium, 1-3-2020]   0.01     1     -1.6      1.7     1803     1975  1.00     0.024   0.016
b[2, clostridium, 2-4-2020]  -0.02  0.99     -1.6      1.6     2065     2036  1.00     0.022   0.015
b[2, clostridium, 1-5-2020]  -0.01  1.01     -1.6      1.6     2126     1940  1.00     0.022   0.016
b[2, clostridium, 1-6-2020]  -0.02     1     -1.6      1.6     1877     1893  1.00     0.023   0.016
However, the order we want is: subject, date, experiment.
Now, to get the desired result, we need to modify the underlying xarray object.
In [13]: dim_order = ("chain", "draw", "subject", "date", "experiment")

In [14]: az.summary(experiments.posterior.dataset.transpose(*dim_order))
Out[14]:
                              mean    sd eti89_lb eti89_ub ess_bulk ess_tail r_hat mcse_mean mcse_sd
b[ecoli, 1-3-2020, 1]         0.01  1.01     -1.6      1.6     2059     1804  1.00     0.022   0.018
b[ecoli, 1-3-2020, 2]            0  0.98     -1.6      1.6     2037     1739  1.00     0.022   0.016
b[ecoli, 2-4-2020, 1]            0  0.99     -1.6      1.6     1940     1898  1.00     0.022   0.015
b[ecoli, 2-4-2020, 2]        -0.07     1     -1.7      1.5     1805     1892  1.00     0.023   0.016
b[ecoli, 1-5-2020, 1]         0.01  1.01     -1.6      1.7     2073     1987  1.00     0.022   0.016
b[ecoli, 1-5-2020, 2]            0  0.98     -1.5      1.6     2063     2059  1.00     0.022   0.017
b[ecoli, 1-6-2020, 1]         0.01  0.99     -1.6      1.6     1981     2062  1.00     0.022   0.015
b[ecoli, 1-6-2020, 2]        -0.02  1.03     -1.7      1.6     2098     2003  1.00     0.022   0.017
b[pseudomonas, 1-3-2020, 1]   0.03  1.01     -1.6      1.6     1884     1970  1.00     0.023   0.016
b[pseudomonas, 1-3-2020, 2]  -0.02  1.03     -1.6      1.6     1985     2035  1.00     0.023   0.016
b[pseudomonas, 2-4-2020, 1]   0.02  1.01     -1.6      1.6     1934     2082  1.00     0.023   0.016
b[pseudomonas, 2-4-2020, 2]  -0.04  1.01     -1.6      1.6     2075     1921  1.00     0.022   0.016
b[pseudomonas, 1-5-2020, 1]  -0.03  0.98     -1.6      1.6     1889     1824  1.00     0.023   0.016
b[pseudomonas, 1-5-2020, 2]     -0     1     -1.6      1.6     1928     1884  1.00     0.023   0.015
b[pseudomonas, 1-6-2020, 1]  -0.01  1.02     -1.6      1.7     2011     1790  1.00     0.023   0.016
b[pseudomonas, 1-6-2020, 2]   0.03  0.99     -1.5      1.6     1990     1930  1.00     0.022   0.015
b[clostridium, 1-3-2020, 1]  -0.01  0.97     -1.6      1.5     1809     1821  1.00     0.023   0.016
b[clostridium, 1-3-2020, 2]   0.01     1     -1.6      1.7     1803     1975  1.00     0.024   0.016
b[clostridium, 2-4-2020, 1]   0.02  1.01     -1.6      1.6     1997     1798  1.00     0.023   0.016
b[clostridium, 2-4-2020, 2]  -0.02  0.99     -1.6      1.6     2065     2036  1.00     0.022   0.015
b[clostridium, 1-5-2020, 1]  -0.02  1.01     -1.7      1.6     2037     1899  1.00     0.022   0.016
b[clostridium, 1-5-2020, 2]  -0.01  1.01     -1.6      1.6     2126     1940  1.00     0.022   0.016
b[clostridium, 1-6-2020, 1]   0.04  1.01     -1.5      1.7     2057     1880  1.00     0.022   0.016
b[clostridium, 1-6-2020, 2]  -0.02     1     -1.6      1.6     1877     1893  1.00     0.023   0.016
Note
DataTree does not implement transpose() directly,
so it must be applied to the underlying Dataset via .dataset.
ArviZ functions accept a Dataset directly, so no re-wrapping into
a DataTree is needed.
Labeling with indexes#
As you may have seen, there are some labellers with Idx in their name:
IdxLabeller and DimIdxLabeller.
They show the positional index of the values instead of their corresponding coordinate value.
We have seen before that we can use the coords argument or
the sel() method to select data based on the coordinate values.
Similarly, we can use the isel() method to select data based on positional indexes.
In [15]: az.plot_forest(schools, var_names="theta", labeller=azl.IdxLabeller());
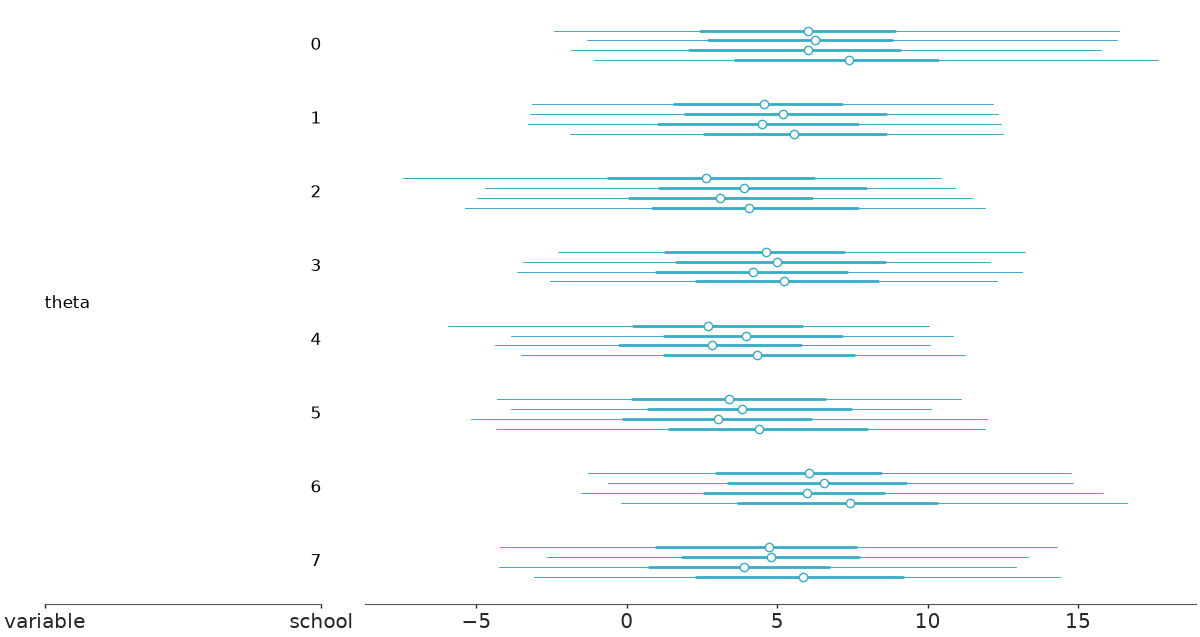
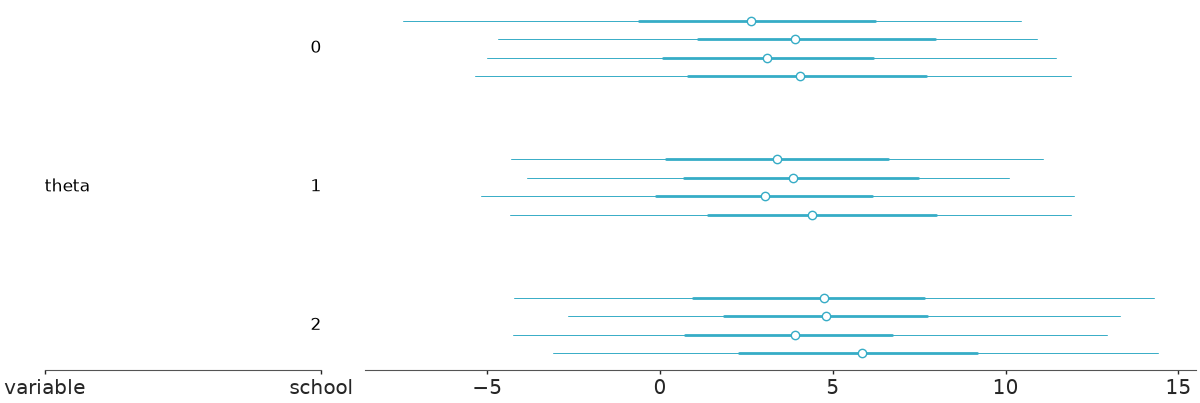
After seeing the above plot, let’s use isel method to generate the plot of a subset only.
In [16]: az.plot_forest(schools.isel(school=[2, 5, 7]), var_names="theta", labeller=azl.IdxLabeller());
Warning
Positional indexing is NOT label based indexing with numbers!
The positional indexes shown will correspond to the ordinal position in the subsetted object.
If you are not subsetting the object, you can use these indexes with isel without problem.
However, if you are subsetting the data (either directly or with the coords argument)
and want to use the positional indexes shown, you need to use them on the corresponding subset.
Example: If you use a dict named coords when calling a plotting function,
for isel to work it has to be called on
original_idata.sel(**coords).isel(<desired positional idxs>) and
not on original_idata.isel(<desired positional idxs>).
Labeller mixtures#
Different labellers can be combined using mix_labellers(), so
that each labeller in the mixture contributes the formatting it specializes
in. This is generally more convenient than writing a labeller from scratch
when you only want to tweak one part of the default behaviour.
Custom labellers#
For full control over label formatting, subclass
BaseLabeller and override the relevant method(s).